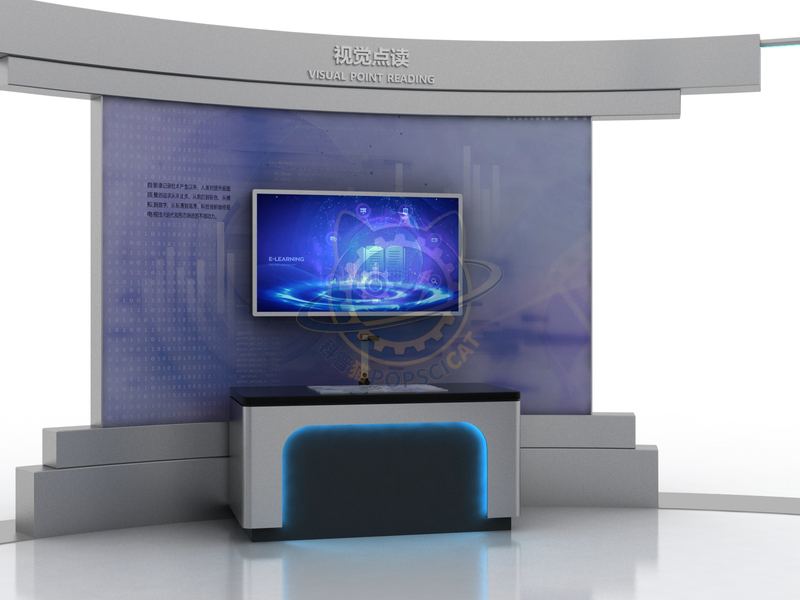
Visual big models are artificial intelligence models designed to understand and interpret visual information.
| Category | Digital & AI |
|---|---|
| Standard size | Custom size |
| Supply | Single unit or batch · OEM to your drawing |
| Lead time | Standard 4–8 weeks after deposit (confirmed per contract) |
| Warranty | 1 year, structure and control |
| Documents | Specification sheet · control diagram · spare-part list |
A standard catalogue model: the dimensions, control package and finish are fixed, which is what keeps the price and the lead time predictable. Size, colour and interface language can be adapted without a new design cycle.
Visual big models are artificial intelligence models designed to understand and interpret visual information. It utilizes neural networks with a large number of parameters to analyze and understand visual content, automatically learning hierarchical structures from a wide range of datasets, enabling it to detect complex patterns and connections in images.
The unit is designed for unsupervised public use: controls are recessed or shielded, moving parts are enclosed, and the interface is operable by a child of about six with no instruction. Where a screen is used, the language can be switched without changing the hardware, and the content can be replaced on site.
Visual big models, also known as deep learning models or visual transformers, are a highly anticipated technological breakthrough in artificial intelligence technology in recent years, particularly demonstrating enormous potential in the field of computer vision. Visual big models are a type of artificial intelligence model aimed at understanding and interpreting visual information. The big visual model operates based on deep learning principles and utilizes neural networks with a large number of parameters to analyze and understand visual content. Intended to automatically learn hierarchical structures from a wide range of datasets, enabling large visual models to detect complex patterns and connections in images. The visual big model is based on neural network architecture, especially the Transformer architecture, which consists of two parts: self attention mechanism and position encoding. The self attention mechanism enables the model to focus on important parts of the input data, while positional encoding helps the model understand the positional relationships of elements in the image. Through these two parts, the visual big model can capture.
Every unit leaves the factory after a running test: mechanisms cycled, electronics burned in, edges dressed, fixings torqued and marked. Wear parts — bearings, sliders, lamps, belts, touch panels — are modular and listed on the spare-part sheet, so a venue technician can replace them without returning the exhibit. Crating is plywood with foam blocking; the loading plan and packing list travel with the shipment.
Other models from the Digital & AI line, all held to the same specification and the same control package.

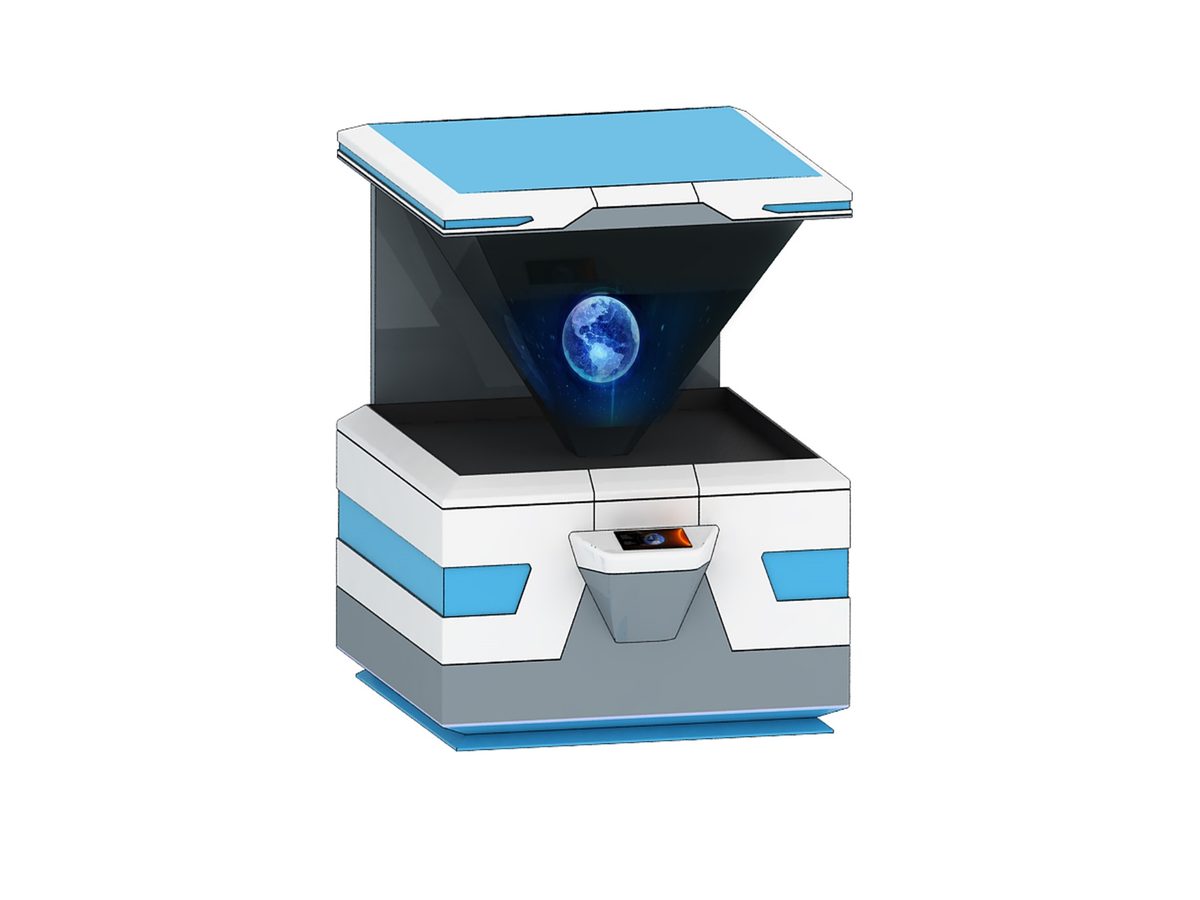
Hundreds of orbiting nodes light up to show global coverage.

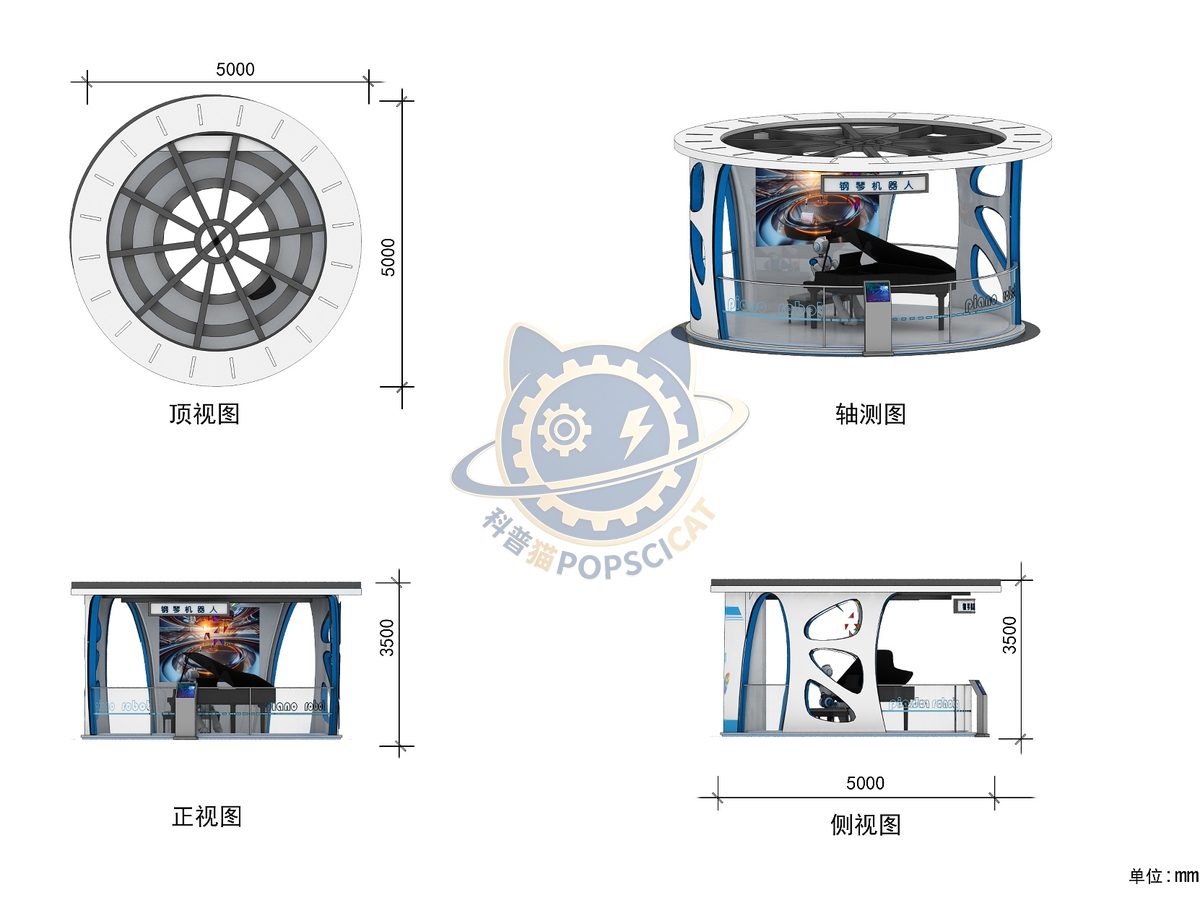
Mechanical fingers play a request chosen by the visitor.

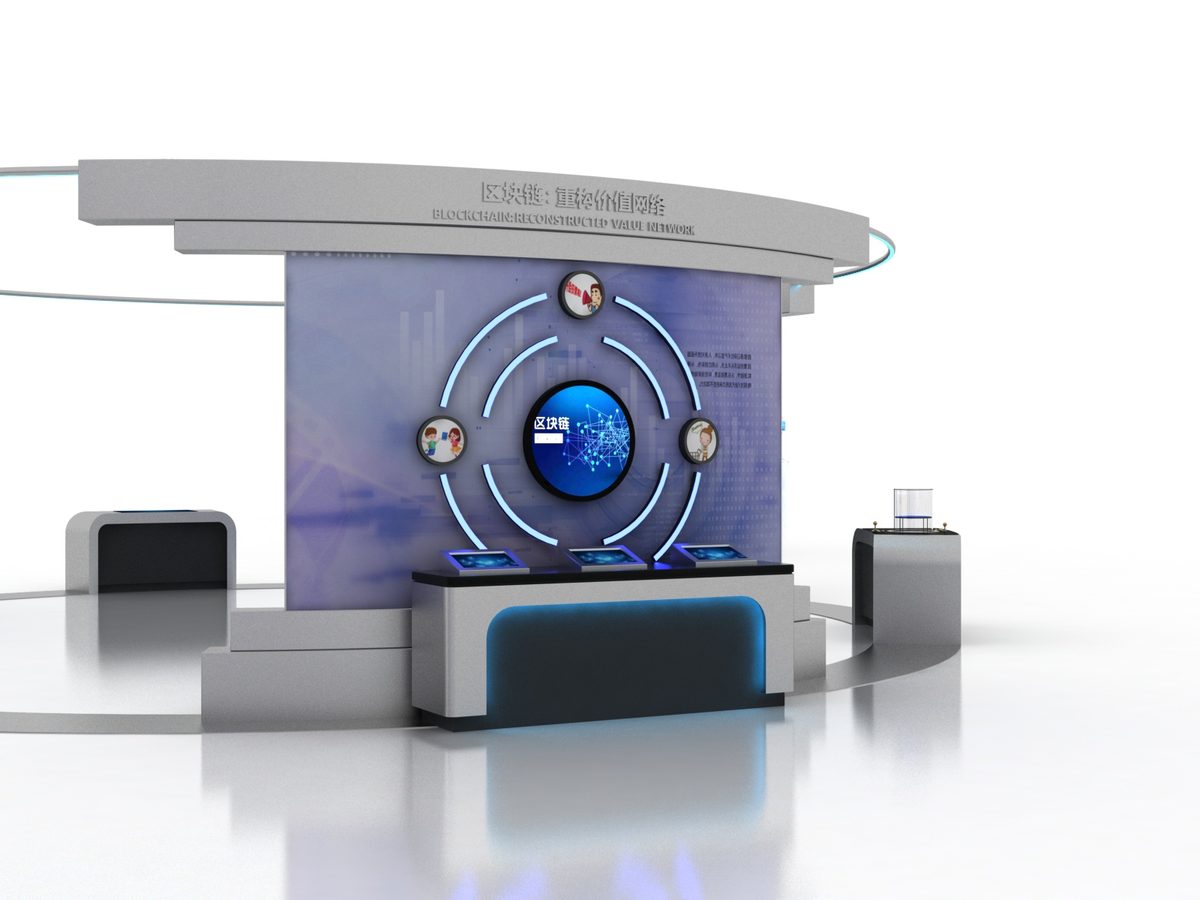
A chain of blocks that cannot be edited once the next one is added.

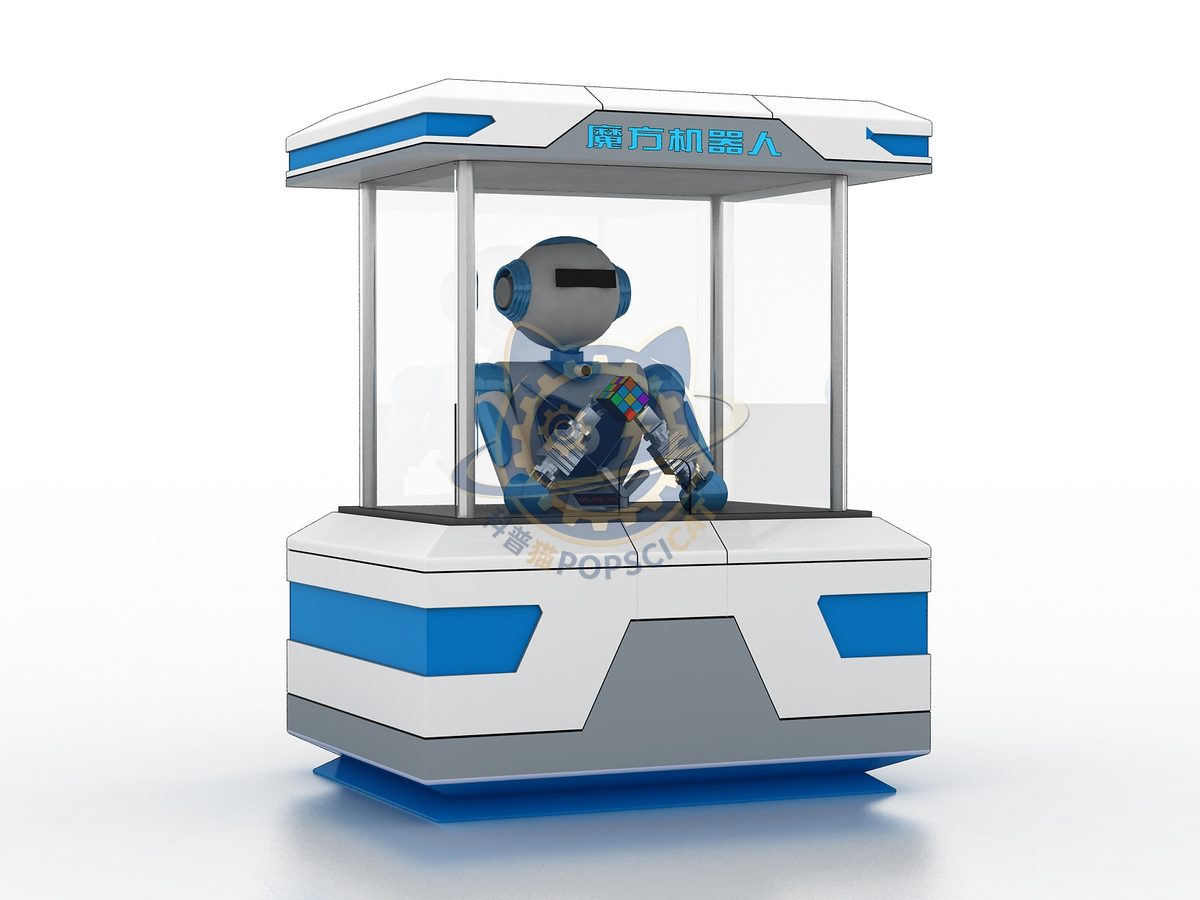
A camera reads a scrambled cube; the arm solves it in under a minute.
Attach a theme outline, a floor plan, or nothing at all — a photo of the space is enough to start. Quotations are issued against a real exhibit list, not per-square-metre guesses.
Scan to add us